This JS toy allows you to play around with different variants of binary search.
Notes
This tool tries to list all the ways that a binary search over a sorted list can work in Python. Unlike C++, Java,
Go, or other languages, this doesn't handle all the variant midpoint calculations. Instead, it focuses on the
boundary conditions. Also unlike most other languages, this code tries to find the "insertion" point for a search
value, rather than the index of the search element. Other binary search implementations return more complex or
more nuanced variants, such as returning negative values in Java, "left" and "right" variants in Python, a
"Result" enum in Rust, etc.
Some conditions appear redundant, especially with lo < hi appearing to be the same as
hi > lo. These variants are meant to help show the code is correct when overloading the operators
with custom implementations; it may be inconvenient to convert a < implementation into a >.
While the generated code shows how to search a list of integers, the code should also work with other types, such as
floats, strings, ranges, etc. This code assumes the range of values is totally ordered.
Several languages have a "spaceship" operator, which can return the full range of comparison operations. This code
currently doesn't use equality, since it isn't strictly necessary, and instead relies solely on the inequality
operators.
Consider the problem of trying to sort Calendar events:
@dataclass
class Event:
    start: int
    end: int

    def __lt__(self, other):
        return self.start < other.start
Suppose we have a binary search implementation that used <= instead of <, to our
dismay. This object doesn't provide an equality method. We could implement it, but that may be impractical to
copy and maintain that code. We could simulate it so that it works with the binary search function:
@dataclass
class Event:
    start: int
    end: int

    def __lt__(self, other):
        return self.start < other.start

    def __lte__(self, other):
        return self < other or (not other < self)
The modified code is less easy to read. Really, it would be better to modify our binary search to use the correct
comparison function.
While working on my Wordle solver, I found a trick for treating integers as little lists. To keep
memory usage down, I decided to pack the 5 letter words into a 32 bit integer. I use 6 bits per
letter, leaving the top bit as a zero. This allows doing some SIMD tricks without having to
expand the nibbles later.
However, sometimes it’s convenient to treat each Wordle word as a variable length list of
characters, rather than the fixed size, 5 letter words that the game uses. Since the game uses
up to 5 letters per word, and each letter consumes a 6 bit nibble, that leaves 32 - (5 * 6) = 2
bits left for use. 2 bits isn’t enough to encode a length field. However, we can use a trick
similar to NULL terminated C strings: 1-bit prefixed ints.
This trick works by treating each 32 bit int as a [0, 5] length string of 6 bit values, prefixed by
a 2 bit prefix. For example:
The A-E bits represent the nibbles representing the letters, while the 01 prefix indicates the
end of the string. To detect the length of the String, we count the number of leading 0 bits
and divide by 6 to get the length:
This is nice because Integer.numberOfLeadingZeros() is a single instruction on Intel
architectures. Additionally, while dividing by 6 would normally be slow, the compiler optimizes
this to a “magic number” division, i.e. a multiplication by (2^32) / 6. On my machine,
calculating the length is around 3ns.
While playing around with local LLM inference, I started to internalize how
the web is going to look in the future. This isn’t a hard bet, but the
incentive structure is now clear that Ads will no longer be the preferred way
of monetizing the web.1 Instead, I see the web continuing to exist as
a pay-per-view model, where most servers reject initial requests with a
405 Payment Required error along with a price.
How We Got Here
Up until about 2023, Google, along with other search engines, was the way
people found information online. Google interleaved ads in the results,
which received clicks, and thus revenue from advertisers. Google’s rise
to prominence stemmed from their ability to distinguish fraudulent clicks from
real clicks from real people. Advertisers picked Google’s ad network over
others due to higher conversion rates, and were happy to pay the premium. This
product is called AdWords.
For the non advertising links, users were redirected to the many websites
across the web. These websites, as they became more popular, needed money to
pay for the rising cost of servers, bandwidth, and staff to keep things
running. For the mass majority of sites, the cost (and traffic) was so low
as to be pennies, and it was just a fun way to be part of the
Internet. For sites that were larger, there were two ways to make money:
Show ads. These started off as text ads, evolved to flashing GIF ads,
and finally as video and picture ads.
Require payment. If a user pays for access, they can participate in the
site.
Making payments on the Internet has always been a barrier to entry. For any
early stage website, ads were the only feasible way to go. Charging for
access would alienate the original user base for a site, making it impractical
to ever switch from free or ads-based, over to a payment model.
Google also made this model of sustaining possible. By putting their ad
snippet in your HTML, Google could show ads in the header, footer, or any
other high visibility space. They would figure out who your site’s audience
is, what ads would do best in their slot, and keep track of payment. Once
a month, if you had enough clicks, Google would cut you a check for your
share of the ad revenue. This product is called AdSense.
How We Broke Down
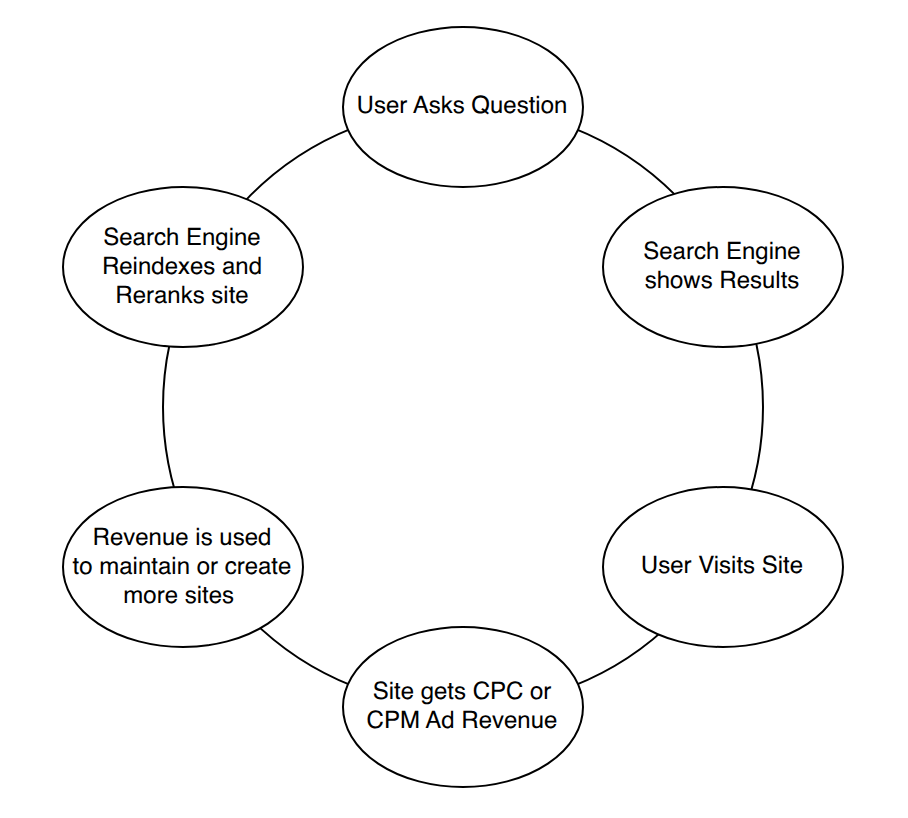
With the proliferation of LLMs, the virtuous cycle of making sites, getting
clicks, earning money, and making more sites, broke down. OpenAI, followed by
Anthropic and others, showed the world there is a better user experience. AI
companies boil down the entirety of the Internet, (and books and everything
else) into a machine that generate text (a.k.a. GenAI). There are two phases
to this process:
Consume all available information. This is the training phase.
Use the trained model, and occasionally query for outside data, to
generate text. This is the inference phase.
As the world turns, so too do trained models become out of date. They must
constantly be re-trained with new information (such as news) to be able to
answer topical questions.2 This has resulted in immense load on the websites
of the Internet, with utterly insatiable demand for all the data available.
Website proprietors saw colossal increases in cost across the board, but with
no humans looking or clicking on their ads.
In other words, almost every site out there is paying higher cost, with
no additional ad revenue to cover.
This might be sustainable in the long run, but I’m betting not. Many
websites have tried to exclude bot traffic, i.e. the machines scraping them,
by using technologies such as Cloudflare and reCaptcha (ironic?). However,
while this may help limit the costs, it doesn’t help with the other
virtuous-cycle breakdown: No more ad revenue.
Google, adopting the UX of OpenAI, started putting their own generated text
at the top of the search results. The starting point for users to visit the
rest of the world wide web is being spawn-camped. I’d bet heavily that
Google’s own outbound clicks from the search engine page is crumbling. With
no more [human] traffic being steered into websites, there is no more ad
revenue to sustain the site. With the ever increasing bot traffic to
websites, the cost is going up. This will not last!
(Aside: I think this change in our technology world is not necessarily a bad
thing. The Tech Industry evolves faster and faster, with outdated ideas
falling before the new innovation. As a user of AI, the LLM snippets are
a better experience. I just want to make sure the Golden Goose isn’t killed
in the transition.)
What Can Be Done To Fix This
Until I started playing around with local LLMs, I kinda knew this world we
live in was not going to last. It seems hopeless to solve, with all the
incentives being upended and no clear part which needs to be changed. The
key idea that made me change my thinking was who was making all these
requests to websites?
LLMs have a weakness: They only know approximate things. Like the
compression artifacts of a JPEG, precise information is hard to capture.
For example, what was the daily high temperature in Los Angeles on August
29th, 1997? The machine knows generally, what temperatures there are,
and generally what temperatures there are in August, and generally
what temperatures there are in Los Angeles. But for specifics, you need
to go the the NOAA [FTP] site to answer this.
Running locally, this problem becomes a lot more apparent. The model itself
is only 20-100 GB in size. Think about that. All the worlds knowledge
boiled down into something that can fit on a thumb drive. Something has
to be removed for it to fit. Unlike the production grade models that
Anthropic, OpenAI, and others run, the local models suffer more from
imprecise knowledge.
To fix this problem, harnesses (like pi.dev) know how to
issue queries to websites and other sources to fill in gaps in their memory.
And, crucially, who is making this query? It’s me. Carl. Not some
faceless megacorp making millions of queries per second, but just me.
We have a chance! Looking back at the virtuous cycle above, website owners
now have a way to ensure they can withstand the influx of load. Not in a
“personalized, hyper targeted panopticon” kind of way, but in a “this is a
real request for knowledge” way.
Carl’s Bet for the Future.
With this in mind, here is what I see for the (hopeful) survival of the web:
Payment Required
Most websites will require a small, almost insubstantial payment for their
services. When accessing a site, it will reject it with
405 Payment Required. Just like a challenge for authentication, our agents
will pay a tiny bit and retry the request with a receipt, finally getting the
data. Scraping the web will flip to being encouraged, with website owners
doing everything they can to invite traffic.
Subscriptions
Rather than every website implementing their own payment solution, I expect there
to be a standardized payment mechanism, perhaps built into the HTTP Spec
itself. Rather than go through the challenge each time, a user will buy a pass
to query an unlimited amount, (perhaps tokens?), and have the cost deducted.
Bulk Data Deals
Reddit was probably the first to sell bulk access to their data. If I recall,
Google paid like $60 Million for unabridged access, in order to train their
model. I suspect deals like this will make sense for much larger sites.
Boutique Data Brokers
Not all data is easily fetched, and some data can only be discovered in person.
I can see a world where custom data is collected and organized by small shops,
and resold for usage by AIs. There will be a large open market for niche data
that LLMs don’t know about, but whose users would like to know. For example:
“Is this restaurant open on Labor Day? Someone can go in person to find out
and publish it via an API.
Where We Go From Here
This change in the world didn’t click for me until I tried
using local LLMs myself. When my harness’s
requests were rejected, I thought “I’d be happy to pay for that, just give me
the data”. Problems such as
overscraping evaporate
when crawlers have to pay for their data. So many problems just disappear. I
think we as a tech community need to agree that the web is in a precarious
state, agree on how we can enable it going forward, and build our tools with
empathy in mind. Website owners need an incentive to keep providing us with
valuable services if we want them to stick around.
I shudder saying this. The web used to be so new and pure that people put things out there just be helpful to others, and as self expression.
I had originally bet that this would make Perplexity AI a serious contender.